Facebook Reels Scraper
Extract the reels of public Facebook Pages and profiles without logging in: caption, hashtags, publish time, play count, reactions, comments, shares, duration, video and thumbnail URLs, subtitle tracks and the Page's details on every reel.
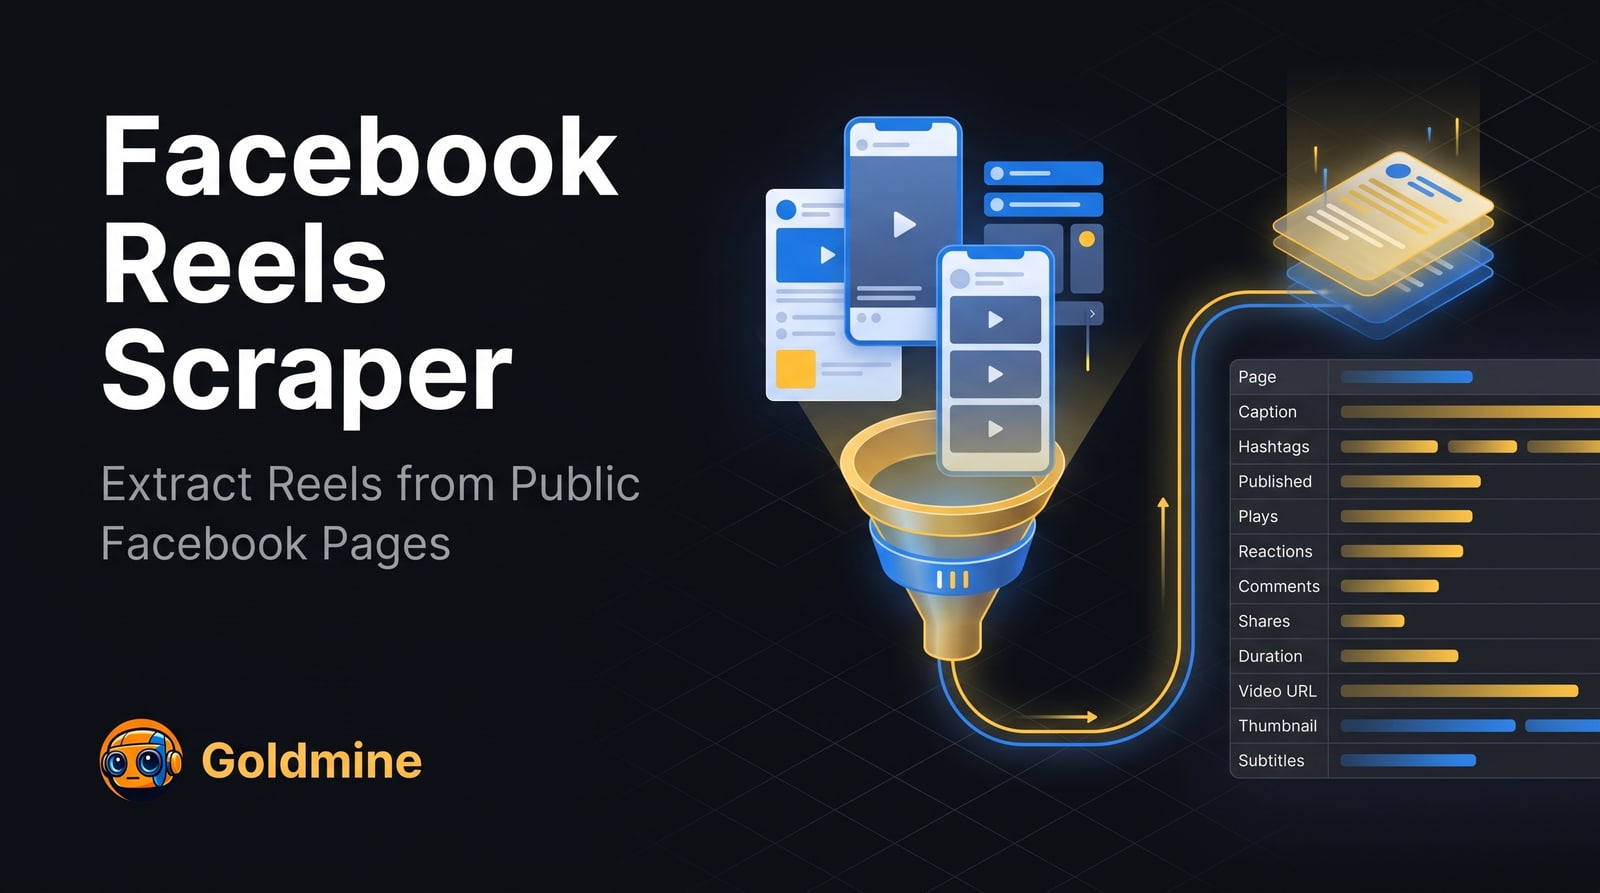
What it extracts
Every field below comes from the Actor’s published dataset schema.
| Field | Description | Type |
|---|---|---|
pageName | Page | text |
caption | Caption | text |
publishedAt | Published | date |
url | Reel URL | link |
playCount | Plays | number |
reactionCount | Reactions | number |
commentCount | Comments | number |
shareCount | Shares | number |
durationSeconds | Duration (s) | number |
thumbnailUrl | Thumbnail | image |
videoUrl | Video URL | link |
hashtags | Hashtags | array |
inputUrl | Input | text |
Input parameters
Generated from the Actor’s input schema — the same fields the Apify console shows.
| Parameter | Type | Required | Description |
|---|---|---|---|
startUrls | array | Required | Facebook Pages or public profiles whose reels to scrape. Paste a page URL such as https://www.facebook.com/natgeo, its reels tab (…/natgeo/reels), a username such as natgeo, or a profile.php?id=… link. One entry per page, and as many pages as you like. |
maxItems | integer | Optional | Maximum number of reels to scrape from each page (start URL), newest first. |
untilDate | string | Optional | Stop scraping a page when its reels get older than this date (format: YYYY-MM-DD). Leave empty to scrape until maxItems is reached. |
proxyConfiguration | object | Optional | Proxy configuration. Facebook serves reels without a proxy, so none is used by default. Switch to Apify datacenter or residential proxies if pages come back blocked. |
API access
Run this Actor from your own code over the Apify API.
{
  "startUrls": [
    "https://www.facebook.com/natgeo",
    "bbcnews"
  ]
}curl -X POST \
"https://api.apify.com/v2/acts/logical_scrapers~facebook-reels-scraper/run-sync-get-dataset-items?token=YOUR_API_TOKEN" \
-H "Content-Type: application/json" \
-d '{"startUrls":["https://www.facebook.com/natgeo","bbcnews"]}'import { ApifyClient } from 'apify-client'
const client = new ApifyClient({ token: 'YOUR_API_TOKEN' })
const run = await client.actor('logical_scrapers~facebook-reels-scraper').call({
"startUrls": [
"https://www.facebook.com/natgeo",
"bbcnews"
]
})
const { items } = await client.dataset(run.defaultDatasetId).listItems()
console.log(items)from apify_client import ApifyClient
client = ApifyClient("YOUR_API_TOKEN")
run = client.actor("logical_scrapers~facebook-reels-scraper").call(run_input={
"startUrls": [
"https://www.facebook.com/natgeo",
"bbcnews",
],
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)Runs are executed on Apify. Create an API token in your Apify account, then call the Actor over REST or with the official client for your language. The same input object works in the Apify console, so you can test interactively before automating.
Pricing
Data not currently verified. This Actor's pricing model is not declared in our source repository.
Current rates are published on the Apify listing and can change, so they are not duplicated here. See pricing on Apify
Reliability
Measured across all public Goldmine Actors on Apify, 2026-08-24. This is an account-level figure, not a per-Actor benchmark — per-Actor speed and completeness benchmarks are not yet published. Source.